Mapping the Detection Coverage Difference Between Behavioral Baselines and Regex Libraries for Insider Threat
Behavioral baselines and regex patterns each miss threats the other cannot see.
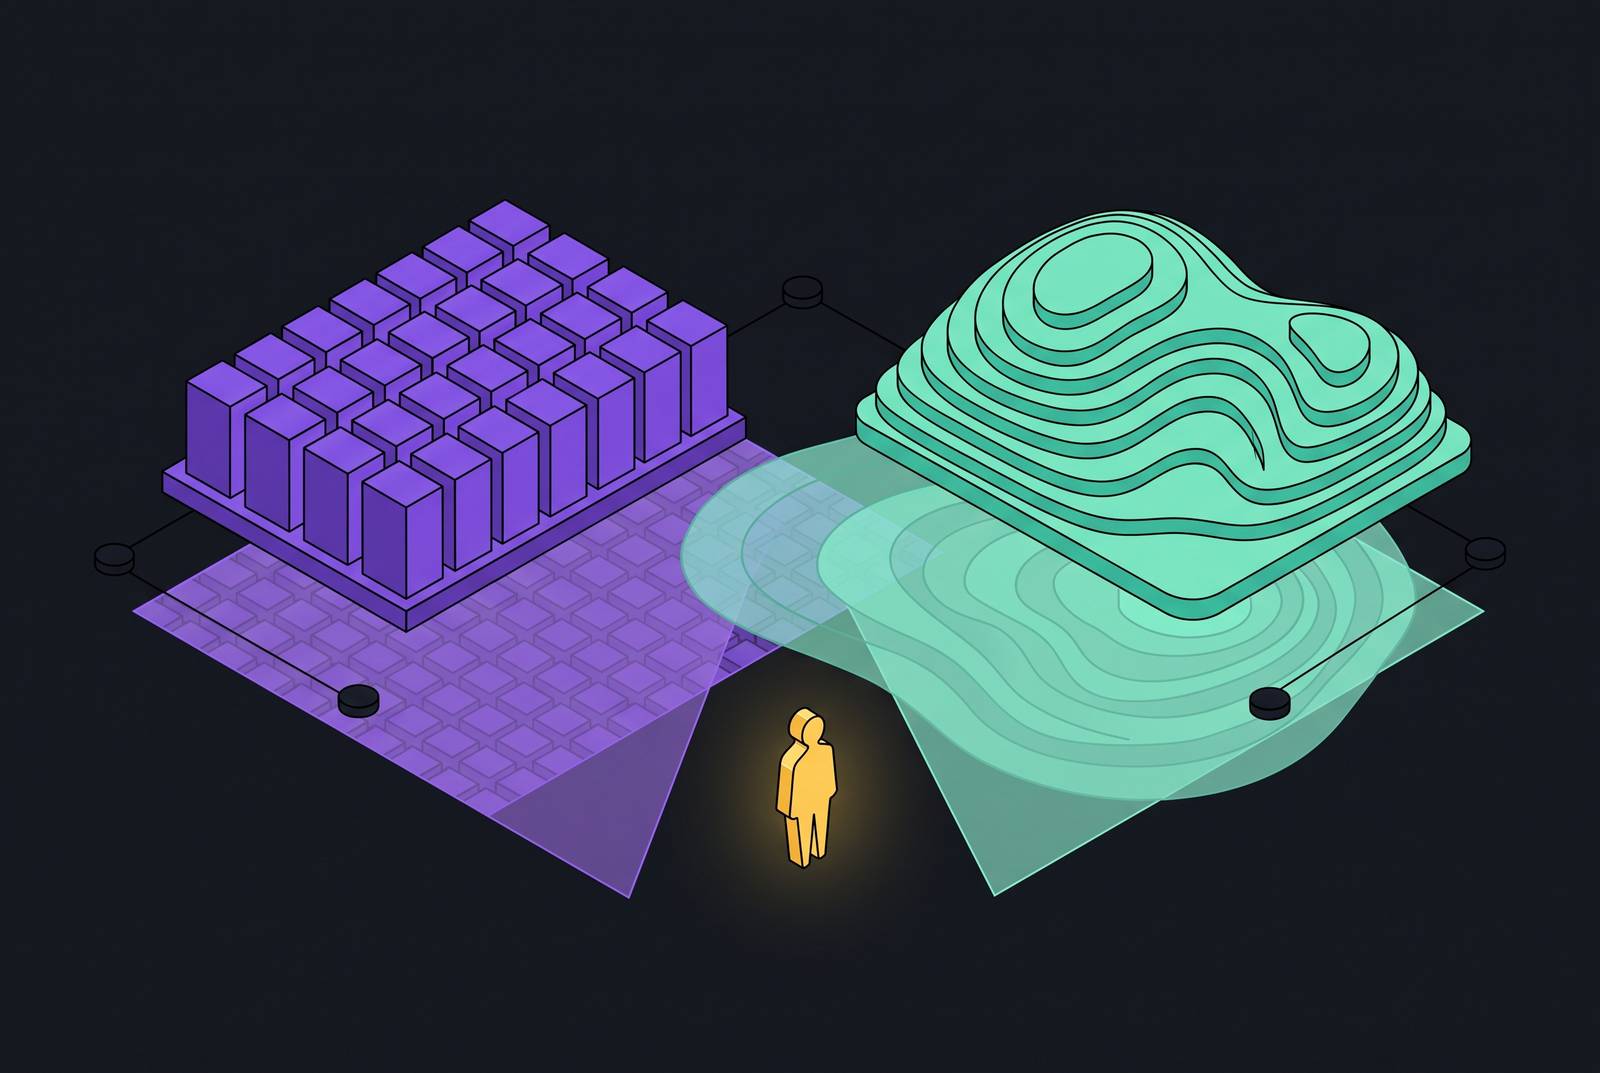
Regex-based data loss prevention and behavioral baselines (UEBA) are the two most widely deployed insider threat detection methods, but both carry a blind spot that tuning cannot fix. Regex catches what matches a known pattern; UEBA catches what deviates from a known normal. Insider threat frequently does neither, so organizations running both still miss the threats that matter most, and closing that gap requires a different detection model: one that evaluates content meaning, identity, role, and timeline together rather than running pattern matching and deviation scoring as separate, parallel checks.
Why regex and behavioral baselines were not designed for the insider threat problem
Insider threat programs rarely fail for lack of tooling. Most mid-size and large organizations already run some combination of regex-based DLP and behavioral analytics, and both categories do real work. But the failure sits further upstream, in the assumptions baked into each tool's design. Regex-based DLP was built to match known patterns: credit card numbers, Social Security digits, keywords on a blocklist. It assumes the sensitive thing looks like something the rule-writer anticipated in advance. Behavioral baselines were built around a different assumption: that threat shows up as a deviation from an established norm. Neither assumption was wrong when the tools were designed. Both are incomplete when applied to the full range of insider threat.
Avatier's 2026 guide on insider threat splits the problem into three categories: malicious, negligent, and compromised. Each fails differently, and each gets caught, if it gets caught at all, by a different mechanism. A malicious insider acting within their entitlement scope looks nothing like a negligent employee pasting a document into a public AI tool, and neither looks like a compromised account operated by someone who stole a legitimate employee's credentials. If you expect one detection mechanism, whether rule-based or statistical, to catch all three, you're asking a single instrument to measure three different things. That's a design limitation, not a configuration problem. No amount of rule-tuning or baseline recalibration closes a gap that exists because the detection model was never built to look in that direction.
What regex libraries catch, and the category of threat they cannot see by design
Regex earns its place in a detection stack. It produces high-confidence, low-ambiguity results in a narrow domain, and within that domain, it's dependable. Structured sensitive data with a known format, payment card numbers, national ID numbers, passport numbers, bank routing numbers, all conform to a predictable syntax, and matching that syntax is precisely what regex is built to do. The same holds for compliance-scoped content where a regulator has already defined what the sensitive element looks like; the rule-writer's job becomes translation, not invention. And when an obvious Social Security number needs to be blocked from leaving an endpoint before anyone reviews it, regex does that job reliably and fast.
Outside that domain, regex doesn't produce a weak signal. It produces no signal at all, and that gap lets sensitive unstructured content pass through undetected because nothing in it matches a rule the system can act on. A sentence like "The acquisition target is a mid-market SaaS company in the healthcare vertical" contains nothing a pattern rule can match, yet it may be among the most sensitive sentences the company has ever put in writing. Unstructured intellectual property, strategic plans, source code narratives, M&A discussion, pricing rationale, competitive analysis, carries no inherent pattern, because its sensitivity comes from what it means, not from its shape on the page.
The same blindness extends to authorization. Vectra AI's insider risk guide describes a bulk-export-to-cloud-storage scenario that only becomes a prioritized signal once behavioral and identity signals are layered on top of the data-movement telemetry; a pattern rule alone cannot see the movement itself when it is routed through an approved channel. GenAI prompt-based exfiltration follows the same logic. An employee pasting internal documents into a public AI platform is moving sensitive content through a sanctioned productivity tool, and the transfer looks like ordinary SaaS traffic to a regex engine, not like data leaving the building. Vectra's guide names this directly: employees feeding internal documents, source code, and strategic plans into public AI platforms represent a blind spot legacy controls were never built to see. Compromised-account activity closes out the list. Avatier's guide describes a compromised insider as an external attacker operating through a legitimate employee's stolen credentials, and every action that attacker takes looks correct to a system that treats successful authentication as proof of identity.
Regex delivers deterministic detection for a finite, well-understood class of pattern-conforming content and nothing outside it. Treating regex coverage as a stand-in for overall DLP coverage means measuring the wrong thing: a clean alert queue in this category says nothing about what's moving through unstructured channels.
What Behavioral Baselines Catch, and the Threat That Never Deviates
Behavioral baselines, through UEBA, were built to catch what regex cannot: threats that carry no structural pattern but do carry a statistical signature. UEBA builds a profile across login times, data access volumes, network connections, peer-group comparisons, and HR context, producing a multidimensional picture of what normal looks like for one specific person. The signal that actually indicates risk is rarely a single anomaly. Avatier's guide points out that off-hours access alone isn't the signal, because volume and timing have to diverge together from that individual's established baseline. Comparing a finance analyst against other finance analysts in the same region, rather than against the whole company, sharpens that signal further and cuts down the noise that comes from ordinary role-to-role variation.
This approach catches things regex structurally cannot. Behavioral analytics also assembles a cumulative pattern across platforms, unusual access spread across Slack, Salesforce, and cloud storage over several weeks, into a single story that no individual-event rule would catch. In cases involving SaaS-based exfiltration, each individual action looked authorized on its own, and the deviation only became visible once you viewed the pattern as a whole.
The approach depends entirely on a deviation existing to detect, and that dependency is where its blind spot lives. Risk that exists from day one, a planted adversary, a new hire who begins exfiltrating data immediately, has no behavioral history to deviate from. Vectra's insider risk guide notes that non-human identities, including AI agents, hold standing privilege and can act autonomously, so some of these entities may never develop a baseline. Slow, authorized exfiltration poses the same problem from a different angle: an insider who moves sensitive data at a pace consistent with their own historical access volume produces no deviation, because the baseline reads the behavior as normal. And when a privileged user legitimately accesses bulk records as part of their job, UEBA will model that access as expected, so a malicious insider who understands how the baseline works can operate inside it indefinitely.
The failure mode here mirrors regex's, inverted. Where regex goes silent on everything outside a known pattern, behavioral baselines go silent on everything inside a constructed sense of normal, and sophisticated insiders, carefully operated compromised accounts, and day-one threats can all live inside that normal for as long as they choose to.
The combined blind spot of regex and behavioral baselines
Running regex and behavioral baselines side by side feels like it should produce full coverage, but the two gaps sit in different structural dimensions, and some threat categories fall into both at once. An organization running both tools can assume that behavioral detection covers what pattern matching misses, and pattern matching covers what behavioral detection misses. But that logic only holds if every threat either matches a known pattern or deviates from normal behavior, and the most consequential insider threats frequently satisfy neither condition.
Negligence illustrates the combined gap cleanly. An employee pasting sensitive content into a public AI tool is using SaaS tools the way they normally do, so it isn't a behavioral deviation, and the content is sensitive by context rather than by structure, so it doesn't trigger a pattern rule either. Vectra's guide names this specific scenario as a blind spot legacy controls were never designed to see. Avatier's guide describes a compromised account as indistinguishable from a legitimate user to any system that treats authentication as proof of identity, and both regex and baseline systems accept an authenticated action as legitimate by default, so the structural problem is that authentication itself is treated as sufficient proof.
The GenAI workflow gap sits outside both approaches simultaneously, which is what makes it the clearest example of the combined blind spot. Content entering a large language model or copilot tool passes through a sanctioned application, carries no structured-data pattern a regex rule could match, and may never deviate from a user's ordinary SaaS usage pattern. Vectra's guide identifies this as a category most programs cannot yet monitor, and it also happens to be one of the fastest-growing exfiltration channels in active use. MERGE-PREV That distinction matters. A false negative is a detection failure inside a known threat model. A coverage gap means the threat model never included the activity now taking place.
Detection signals the coverage gaps require beyond either approach
Closing these gaps calls for detection inputs that neither pattern matching nor deviation scoring was built to generate: semantic understanding of what content actually means, identity and role context attached directly to data movement, and behavioral correlation that spans a user's full activity across systems, measuring more than distance from one baseline.
Semantic content understanding addresses the problem of unstructured intellectual property that carries no pattern a regex rule can match. M&A discussion, competitive strategy, and source code intent require a detection layer that reads for meaning, not shape, since a sentence describing an acquisition target is sensitive because of what it says, not because it fits a template. The same logic applies to inspecting GenAI prompts: judging whether a prompt contains sensitive internal information requires understanding the content itself, something no keyword list or structural pattern can substitute for.
Identity and role context, layered onto data movement, close a separate part of the gap. The real question behind any access event is whether a specific action from a specific identity is consistent with what that identity is actually supposed to be doing, and answering it requires visibility into a person's role-of-record, not just their behavioral history. Avatier's guide identifies the highest-signal indicators as access-pattern anomalies: off-hours mass downloads, access creep, unusual privilege requests, and activity that diverges from a person's documented role. None of these are baseline-deviation signals in the UEBA sense. They're role-context signals, and reading them correctly requires knowing what a role is entitled to do.
Cross-system correlation across a full timeline matters just as much. Vectra's lifecycle model holds that a working program monitors every exit path, web, email, endpoint, and SaaS, rather than only the path where a rule happens to be deployed. A program watching one path leaves the rest open, and exfiltration finds the unmonitored route. Day-one risk, where no behavioral history exists yet, planted adversaries, new hires acting immediately, AI agents operating with standing privilege, cannot be caught through deviation. Detection in these cases has to depend on what an action means relative to the role and the data involved, evaluated with no prior behavioral profile to compare against. Vectra's guide points out that non-human identities, including service accounts and AI agents, may never develop a behaviorally meaningful baseline, so role-and-data context is the only detection surface you have for that category.
A combined, context-aware detection model for what each approach misses
Closing the coverage gaps outlined above requires combining semantic content understanding, identity and role context, cross-system behavioral correlation, and timeline-based investigation into one decision, not as a stack of separate tools checked in sequence, but as a single evaluation of content, destination, identity, role, and surrounding pattern together. The risk in any data movement event lives at the intersection of five things: what the data means, where it's headed, who is moving it, what they're authorized to do, and what the surrounding activity looks like. No single detection layer captures all five at once, so single-mechanism approaches, regex or behavioral alone, leave risk invisible no matter how well you tune each one.
Detection accuracy alone doesn't resolve the problem either. A platform that surfaces the correct alert but leaves analysts to stitch together disconnected log entries across five systems hasn't actually solved anything; the full story, content, identity, role, pattern, and timeline, needs to arrive pre-assembled at the moment of alert, with reconstruction by hand happening afterward instead. Candor's own product documentation describes this directly: its AI agents weigh a user's entire activity timeline and escalate only the cases that genuinely warrant attention, with context already assembled rather than left for an analyst to piece together, and the company states this approach has reduced mean-time-to-investigation by 80%.
Candor's approach reflects this structural incompleteness directly. Rather than relying on pattern matching or statistical deviation alone, the platform layers behavioral profiling with context-aware detection across identity, data meaning, and surrounding activity into a single decision model, which is designed to catch what neither mechanism alone would surface. The GenAI exfiltration blind spot shows why data-movement telemetry by itself isn't enough: a behavioral DLP platform that combines content analysis with account context and activity patterns can flag sensitive information moving through sanctioned channels in ways that diverge from a user's role and history, catching a transfer a regex engine would read as routine SaaS traffic. And because building a stable baseline takes time, day-one threats, newly hired employees, planted adversaries, or people whose roles just changed, can slip through any system that waits for behavior to look statistically unusual before acting. Detecting insider risk without depending solely on behavioral baselines means layering identity, data classification, and surrounding activity together, so a threat can be identified even when the behavior itself looks perfectly ordinary. On shadow AI, Candor's controls act on data, destination, account ownership, and context, intervening before sensitive information leaves; this depends on more than visibility alone or a blanket ban on AI tools, matching the control architecture the GenAI blind spot actually calls for.
Vectra's lifecycle model offers a useful sequence for thinking through how this all fits together: classify the organization's crown-jewel data first, reduce unnecessary access to it, monitor every exit path, assess the intent and context behind anomalies, then respond, contain, and feed what's learned back into the system. The order isn't incidental. Classification determines what the detection layer should be looking for in the first place, and monitoring without classification produces noise instead of signal. A combined detection model is only as good as the classification work that tells it what the organization's crown jewels actually are, including the intellectual property that carries no label at all because its value comes from context rather than structure, and that classification work is the precondition for everything described above. Programs that buy a monitoring platform before doing that classification work, before defining risk appetite and agreeing on who responds to what, tend to generate exactly the kind of noise this piece has been describing.