Coverage Gaps That Open When Classification Debt Accumulates Faster Than Tagging Programs Can Close
Classification gaps leave security controls blind to the data that matters most.
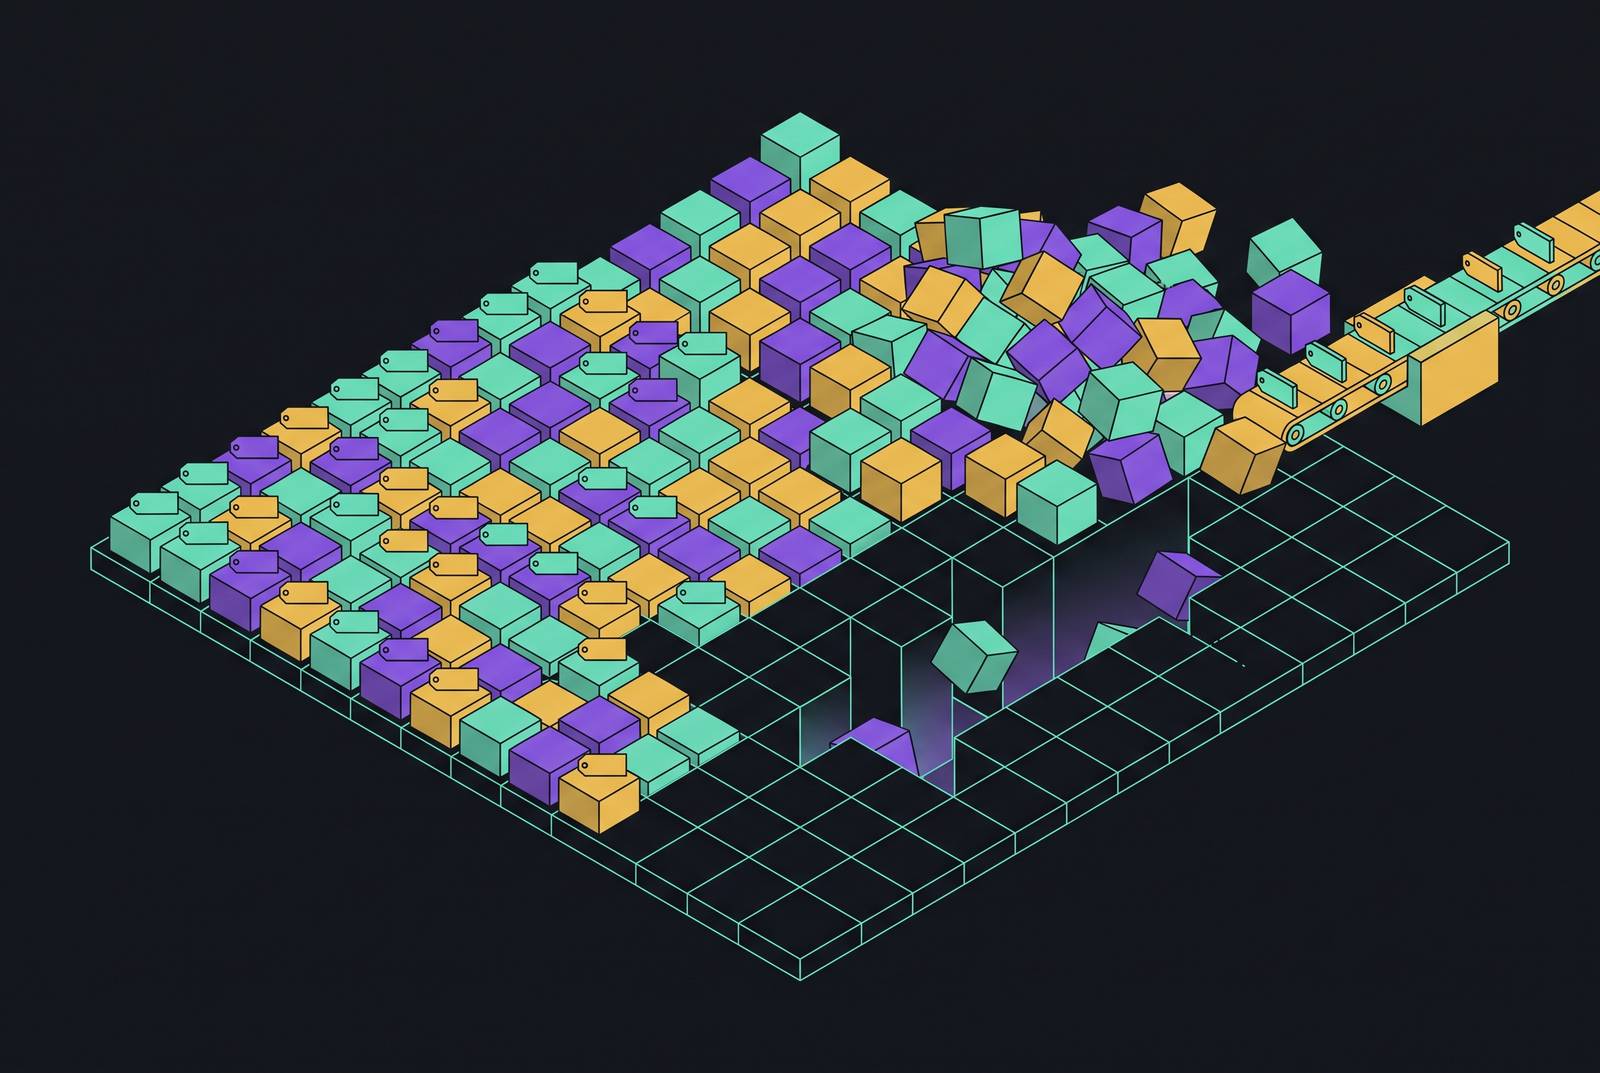
Classification debt is the gap between the sensitive data a company actually holds and the sensitive data it has found, labeled, and put under governance. That gap is a visibility problem: DLP, insider risk detection, and access controls can only act on data they can see, and a label is what makes data visible to them. When the label is missing, the control is blind.
Classification debt is a protection problem, not a paperwork problem
The common way to talk about classification debt treats it like an audit liability: a regulator eventually finds the unlabeled folder, writes it up, and the company pays a fine or signs a corrective action plan. That framing undersells what is actually happening. Unlabeled data is ungoverned data: no control in the security stack currently knows it needs protecting. DLP systems match content against rules built on classification tags. Insider risk platforms build behavioral baselines around what's sensitive and what access to it should look like. Access governance tools decide who should reach what based on how a resource was classified when it entered the system. Without a label, every one of those systems loses its anchor point.
Discovery and classification work as a dependency chain, not two separate projects. Discovery answers where data lives and what it is. Classification answers what rules apply to it once it's found. When either step is skipped, the rest of the governance program, however well designed, only reaches a fraction of the real data estate. A company's most valuable information often carries no label because it was never going to trip a regex or match a predefined compliance category. A classification program built around spotting known patterns has no reason to ever flag them.
Data estates growing faster than tagging programs can scan them
Classification programs run on cycles: a scan, a scoping exercise, a batch of labels applied, then a wait until the next pass. Enterprise data estates don't wait. New files, new databases, new SaaS tenants, and new pipelines get created every day, continuously and without pause for the next scan window. That mismatch, periodic effort against continuous growth, is what produces classification debt, and it produces it by design rather than by neglect. No amount of added headcount on the tagging team changes the shape of the problem, because the problem is architectural: a batch process can never fully keep pace with a continuous one.
Two failure modes compound inside that mismatch. A label assigned early on says nothing about what the data became much later.
Shadow data is what coverage drift looks like in practice: copies that business units create for their own convenience, exports pulled from systems the company has since deprecated, data loaded into SaaS tools that were never approved through a formal process. All of it accumulates in places the governance program never put on its map. It was never a candidate for classification to begin with. Discovery duplication makes the problem worse still. The same sensitive dataset often exists in multiple systems at once, each with its own access controls and its own classification status, and a copy sitting in a development environment frequently carries far weaker protections than the production record it was pulled from.
AI ingestion pipelines, agentic access, and the debt timeline
AI agents don't wait for a scan cycle, and they don't query data the way a person browsing a file share does. They reach for whatever a task requires, at whatever speed the task demands, and they typically run under service account permissions that are broad by default. That means any dataset an agent can reach, if it was never classified, is immediately exposed to that access rather than merely scheduled for eventual review. The exposure is live the moment the agent runs.
This changes what unclassified data actually is in practice. IBM's Cost of a Data Breach Report found shadow AI was involved in roughly 20% of breaches, and those incidents cost more than the global average. The exposure in those cases traces back to data that existed and was simply never found before an agent, or a person using an agent, reached it.
The debt also compounds in a way manual tagging programs were never built to track. Agentic workflows generate new artifacts as they run: embeddings, model outputs, cached chunks pulled during retrieval. None of these artifacts existed when the last classification scan ran, and none of them enter scope automatically just because they derive from sensitive source data. Each run of an AI pipeline can mint new unclassified assets faster than any scan cycle could pick them up, adding fresh debt on top of debt that was already accumulating before the pipeline existed.
Coverage gaps that blind DLP controls to the data that matters most
DLP systems work correctly, even when they fail to protect the data that matters most, because the engine is only as good as what it's told to look for. When a file carries no classification label, DLP has nothing to match against, so it passes the file along without raising a flag, because it was never given the information it needed to act.
Compliance-driven classification programs prioritize PII, PHI, and PCI because regulations spell those categories out explicitly, and that prioritization makes sense on its own terms. A company can run a DLP program that covers every regulated category completely and still leave its most valuable intellectual property fully exposed, because that property was never going to match a predefined regex or structured data pattern.
Picture how this plays out with a credentialed insider. A data scientist with legitimate access queries a sensitive but unlabeled dataset. Every single step she takes falls within her permitted access level, so nothing about the access itself looks wrong. DLP, built to inspect content and flag unusual egress patterns, logs nothing unusual, because there was never a classification marker telling the system that this particular dataset deserved scrutiny. The system did what it was built to do, just not for this case.
Shadow AI opens a parallel version of the same channel. Labels are what bridge discovery and control. Without them, DLP, insider risk detection, and access governance are all operating on an incomplete picture of the estate, no matter how well each tool performs on the data it can actually see. Behavioral DLP platforms that pair content understanding with profiling across cloud storage, email, and endpoint activity can pick up sensitive movement even when a label is missing or out of date, and Candor is one example of a platform built around that approach rather than around static, label-dependent rules.
Label staleness and its effect on insider risk detection
Insider risk detection depends on two things: knowing what counts as sensitive, and knowing what normal access to it looks like. Stale or missing labels corrupt both sides of that equation at once. Behavioral systems work by spotting deviations from an expected pattern, but an expected pattern can only exist for data that has actually been characterized. Access to a dataset with no classification has no established baseline, so there's nothing for the system to compare against and nothing for it to flag as unusual.
Google's Facade system, running internally since 2018, shows what good detection looks like when this problem is solved. Without that inventory, the same modeling approach has nothing to model.
Label staleness produces a specific and dangerous version of this failure. A dataset classified as "internal" three years ago may now contain trade secrets absorbed through an acquisition, or model weights that didn't exist when the label was first applied. Warning signs in insider risk cases rarely live inside one alert or one data source. Warning signs appear when a team can connect activity across identity systems, endpoints, cloud platforms, and data access logs over time, and if the data at the center of that activity was never discovered or classified, the behavioral thread is missing a node it needs to hold together. Risk can be present from the very first day of access, stay statistically normal when viewed in aggregate, or occur entirely through access the person was formally authorized to have. None of those patterns are catchable by a system that doesn't know what the accessed data actually is.
Why more tagging is the wrong response
The obvious response to all of this is to classify faster: hire more analysts, run more scans, close the backlog. That response fails because the math doesn't work. The rate at which new data gets created structurally outpaces what any human-paced tagging effort can keep up with, so the backlog doesn't shrink, it just moves.
The trade-off a security program faces is a real either-or. Enforce policy only on data that's already classified, and most of the estate stays unprotected. When everything must be classified by hand, the program stays permanently behind while the estate keeps growing underneath it. Manual tagging also introduces its own accuracy problems on top of the pace mismatch: human taggers apply labels inconsistently, assign them at the moment of creation without accounting for how data changes afterward, and have no realistic way to revisit a backlog that grows faster than they can work through it.
Automated classification at scan time helps with coverage, but it doesn't fix staleness. A label assigned the moment data is first discovered doesn't update on its own when the content changes, when the file gets copied to a new system, or when its importance to the business grows well past what it was when first tagged. And because most tagging programs are built around compliance categories first, regulated data gets labeled while unregulated but genuinely high-value intellectual property gets pushed to the back of the queue indefinitely. The data carrying the most business risk often ends up the last data in line to get covered.
Protection programs without a complete label inventory
Protection against exfiltration can't wait for a complete label inventory to exist, because that inventory, given everything above, will likely never exist. Controls need a way to reason about what data means, where it's headed, and who's touching it, independent of whether a label was ever attached to it.
Content-aware controls offer one half of that answer: they assess sensitivity by looking at what a file or dataset actually contains, rather than relying on a label someone assigned at some earlier point. That approach covers both the unlabeled case and the stale-label case that rule-based DLP structurally misses. Destination and context carry just as much signal as content does. Data headed to a personal cloud account, a consumer AI tool running under someone's personal login, or an external recipient the company has no prior relationship with is worth scrutiny regardless of what classification tag, if any, the underlying file carries. Candor's approach, built around understanding what's moving and where it's going rather than matching it against a predefined label, reflects this logic directly.
Behavioral context around the person involved is the second necessary piece. A single access to an unlabeled dataset tells you almost nothing on its own. That same access, preceded by unusual search activity, followed by a large export, and carried out from a personal device outside normal working hours, forms a pattern, and patterns are detectable even in cases where no single event would raise a flag by itself. The investigation needs to arrive with that behavioral thread already assembled.
What security teams should audit now
The practical response to classification debt is an audit of where protection currently depends on labels to function, followed by targeted work to reduce that dependency for the data that carries the most risk. Start by checking which DLP rules and which insider risk policies only fire on content that's already been classified, because those rules mark the exact blind spots classification debt has created inside the existing stack. From there, build an inventory of where new data sources have entered the environment without ever entering discovery scope: cloud storage added during a migration, SaaS integrations a business unit approved on its own, AI pipelines reading and generating data with no governance touchpoint anywhere in the process. Coverage drift tends to cluster in whatever infrastructure got added most recently, so that's where to look first.
From there, name the highest-value unlabeled intellectual property directly, trade secrets, unreleased product data, proprietary models, negotiation materials, since this is the data most likely to sit at the back of the tagging queue and, not coincidentally, the data most likely to be targeted. Protecting it shouldn't wait for the classification program to eventually reach it. Label drift appears most reliably in labels attached to data whose content changes often: development environments, data warehouses taking in new feeds, and systems aggregating data from a recently acquired entity.
Finally, test whether current controls actually work against the unlabeled case, not just the labeled one. Run a simulation that moves sensitive but unlabeled data through the channels most often used in real exfiltration incidents, generative AI tools, personal cloud accounts, removable media, and check whether anything fires based on content and behavior rather than on the presence of a label. That test is the most direct way to find out whether the gap this article has traced is real inside a given environment, or whether it's already been closed.