Document Fingerprinting Approaches for Protecting Unlabeled IP
Fingerprinting recognizes specific assets that traditional DLP rules cannot detect.
Document fingerprinting protects unlabeled IP by recognizing specific content rather than looking for a category, format, or classification tag. Fingerprinting establishes what moved, while behavioral detection establishes whether the movement represents risk. For a program to work, it needs both, along with ongoing asset registration and the evidence needed to investigate each alert.
Why so much enterprise IP has no label and cannot be seen by pattern-based controls
Most enterprise IP is never formally classified. Source code, engineering designs, deal models, research notes, and strategy decks can therefore move toward an exit without giving a legacy DLP policy engine a recognizable signal. Their sensitivity comes from their meaning to the business. A paragraph of unreleased strategy has the same value with or without a classification tag. It simply lacks the marker on which a category-based control depends.
Pattern matching asks whether content looks like a known category, such as PII or PCI data. Proprietary content presents a different question, which is whether this is a particular asset the organization needs to protect. An untagged model artifact or pasted source code may have no regex match that answers that question. The content remains sensitive even when the control has no category for it.
AI workflows widen this gap because sensitive content can move through an interaction. An employee may paste a merger model into a chat, an assistant may summarize a confidential contract, or an agent may retrieve a code repository. Custom AI assets, including fine-tuned model artifacts and curated embedding stores, add more unlabeled IP to those paths. Without fingerprinting, the policy engine is blind to the assets that create the most enterprise value.
How pattern-based DLP creates a detection ceiling that tighter rules cannot fix
Static DLP rules fail in two directions. Tightening them increases false positives until analysts begin treating alerts as noise, while loosening them allows real leaks through. Neither adjustment changes what the rules can recognize. A rule such as “block any email containing more than ten credit card numbers” has a clear condition, but a paragraph of unreleased strategy does not satisfy it. Writing more rules of the same kind cannot supply the missing identity of that paragraph.
Broader conditions can draw more unstructured content into the alert queue, but that does not establish which content belongs to the organization or why it matters. Narrower conditions shrink the queue by leaving out material, including valuable IP that has no matching pattern. The resulting false-positive spiral also has a human cost. When analysts learn to ignore signals, the detection gap grows.
Single-vector enforcement has another weakness because content can still move through another path when one is blocked. The Intel case involving Jinfeng Luo illustrates that distinction. DLP blocked one attempt, but Luo used another device, and thousands of sensitive files still got out. Content recognition must work beyond category matching and cover more than one exit path.
What document fingerprinting actually does — creating an identity signature rather than a category match
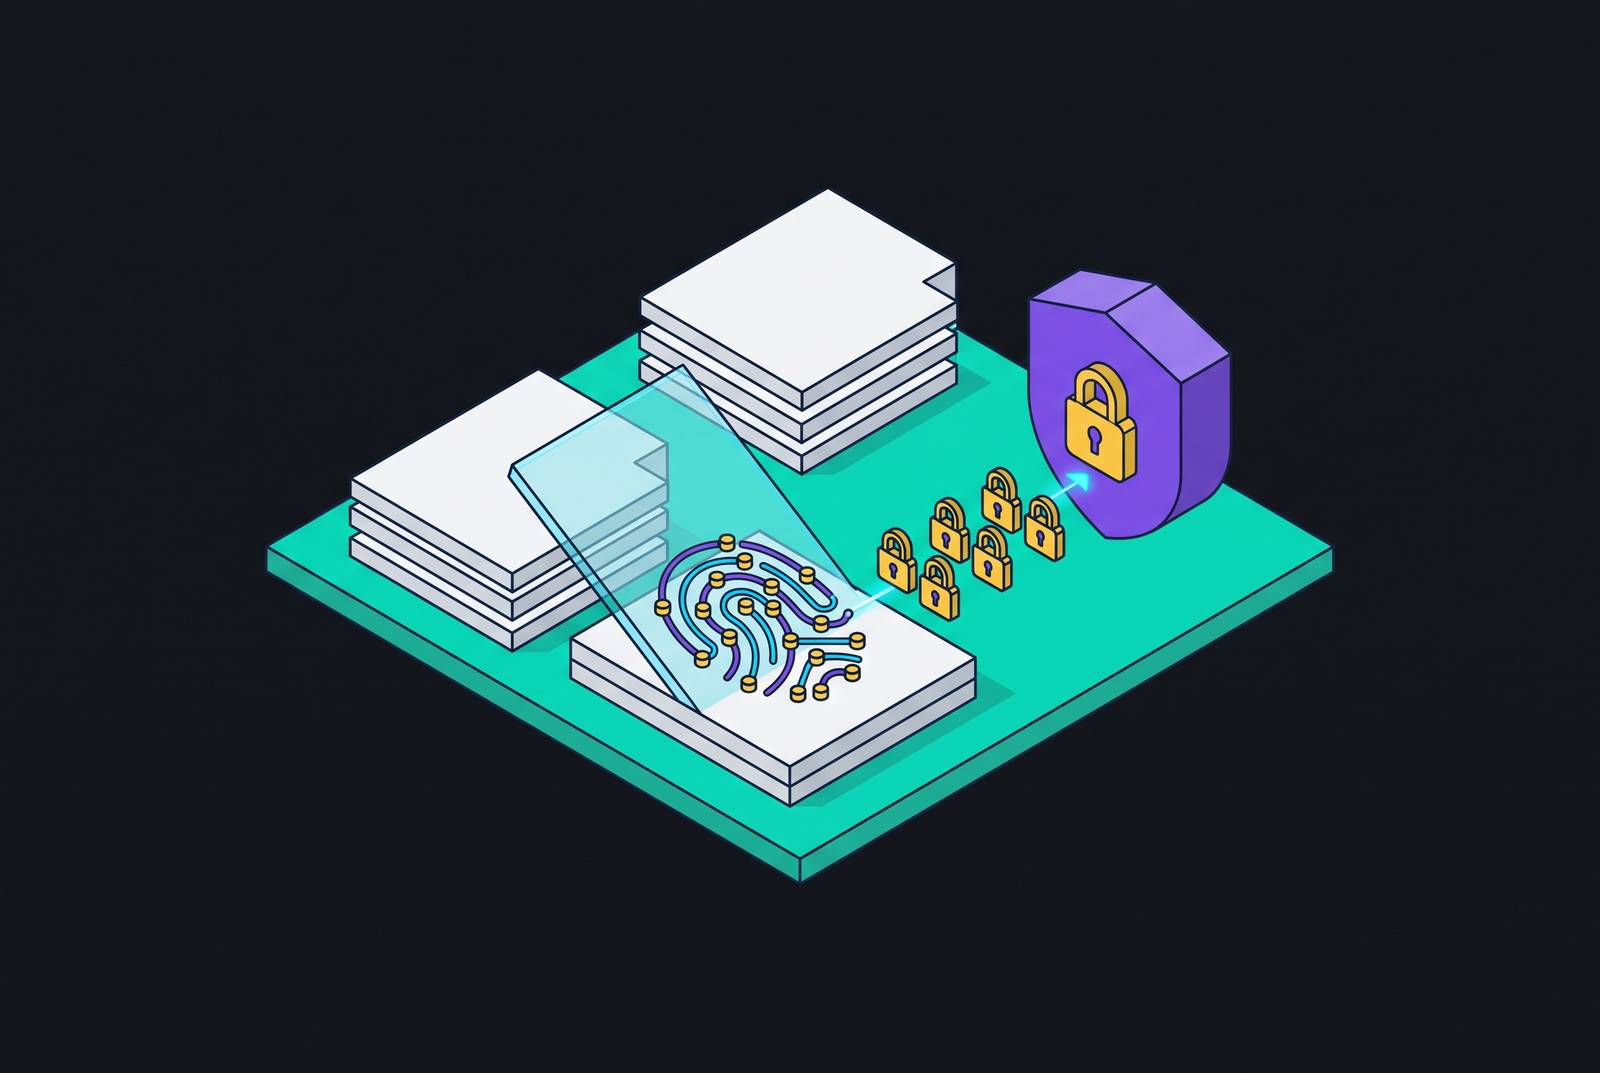
Document fingerprinting generates a durable mathematical signature of a specific asset. That signature lets the system recognize registered content later, even when the file is renamed, reformatted, or only partly copied. The control therefore answers an identity question rather than a category question. It does not need the asset to resemble a credit card number or carry a classification tag. It needs a registered representation of the content against which a later occurrence can be matched.
The process begins by normalizing the asset into a stable representation. Normalization removes variation such as whitespace and encoding differences that should not change the content’s identity. The system then generates a hashing or token-based signature over that representation. A partial-match index supports recognition of fragments.
Registration also defines the recognition boundary. An asset outside the registered set has no fingerprint against which the system can compare its later appearance. Protection therefore depends on both the signature and the currency of the set it represents. It also spans three data states, which are data at rest in the corpus registered in advance, data in use in a live prompt or uploaded file, and data in motion in a request or returning response.
Classification and pattern rules work for categories, while fingerprinting recognizes the organization’s specific assets. The two controls answer different questions about the same content.
The two fingerprinting families and what each one is built to protect
Structured Exact Data Matching (EDM) and Indexed Document Matching (IDM) address different shapes of enterprise data. EDM works with structured data, the rows held in a system. IDM serves unstructured files, the content held in repositories. The first decision is therefore about the asset’s shape. Conflating the two can leave the most important unprotected assets covered by the wrong kind of matching.
If the critical asset consists of structured records, EDM is the relevant family. If it consists of design documents, board decks, code modules, or research datasets held as files, IDM is the relevant family. IDM fingerprints those files and can recognize the whole original or a meaningful piece of it. That makes it directly relevant to unlabeled IP whose sensitivity cannot be inferred from format.
Partial matching is the capability that makes this distinction operationally important. An excerpt pasted into a chat, a reformatted proprietary document, or a section of source code copied into a new file can still match the indexed original. AI-era assets, including custom evaluation sets, fine-tuned model artifacts, training corpora, and curated embedding stores, also carry distinct content signatures that IDM can register. Together, EDM and IDM address the two shapes proprietary data takes, namely rows in a system and files in a repository.
Where fingerprinting alone hits its own ceiling and what behavioral context adds
A fingerprint hit establishes what is moving, but it does not establish that the movement is improper. An authorized user may move a registered file through a normal channel at a normal time as part of legitimate work. Treating every partial match as an incident would generate false positives at a different layer. The match provides evidence of content identity for an assessment of intent or risk. That distinction is the turning point from recognition to detection.
Fingerprinting and static rules can both miss risk when activity looks authorized. A user can log in with valid credentials, access data they seem to be allowed to use, and move it through approved channels. Those facts may satisfy the controls even when the activity differs sharply from the user’s established pattern. Behavioral analytics adds that comparison. It evaluates the movement in relation to the user’s activity rather than relying only on the validity of a single event.
The Tesla case involving Guangzhi Cao shows why the surrounding pattern matters. Cao copied a massive trove of Autopilot source code files and directories to his personal iCloud account and also admitted to storing files on a thumb drive before leaving. How much was moved and where it went tell more than a content match alone can. In a different archetype, an insider exfiltrating customer lists, pricing details, and employee information through Slack, Salesforce, and Google Drive over four months required correlation across systems and time. Fingerprinting identifies the assets in those events, but the risk lies in the pattern around them.
How fingerprinting integrates with behavioral detection to surface exfiltration that neither control catches alone
The effective architecture pairs content identity with a behavioral timeline. A fingerprint hit establishes which registered asset appeared, while the timeline shows whether its movement fits a normal pattern for that user, role, destination, and period. These layers constrain each other. Content identity gives behavioral analysis a specific asset to assess, and behavioral context helps show what the match means for risk. Neither a generic anomaly nor an unexplained fingerprint hit offers the same basis for judgment.
Within this combined path, fingerprinting narrows the candidate signal to known registered assets. Behavioral detection then assesses whether the user has previously touched that asset class, whether the volume is unusual for the role, and whether the destination is a personal account, an unsanctioned AI service, or an external party. It also considers whether the event follows reconnaissance activity over the prior weeks. The comparison is therefore not limited to whether access was allowed. It asks whether the sequence is consistent with established use.
Applied to the Tesla archetype, content recognition would establish the identity of the source code, while behavioral context would assess the volume and personal destination. In the multi-platform SaaS archetype, the same architecture would link the assets it recognized across Slack, Salesforce, and Google Drive over the longer timeline. Shadow AI adds a visibility condition to this model. An employee pasting registered IP into a personal AI assistant on an unmonitored channel requires content-level recognition and judgment about the channel, account, and pattern, but neither can operate on an interaction the control cannot see.
AI-assisted investigation makes the combined architecture tractable at scale. The alert should arrive with the assembled story of what moved, who moved it, what happened before and after, and where it went. A platform that identifies the right candidate but leaves analysts to reconstruct that timeline manually still leaves them spending time assembling the context needed to investigate. The payoff is lower mean-time-to-investigation, fewer hours analysts spend piecing together context, and a smaller set of high-confidence alerts in place of a large queue of fingerprint hits waiting for review.
What a fingerprinting program requires to protect unlabeled IP in practice
A fingerprinting program starts with an asset inventory that must be kept up to date as part of ongoing work. The recognition set covers only registered content, so it leaves IP unprotected while it circulates before registration. The inventory must include traditional documents and code as well as model artifacts, evaluation sets, and training data. New code commits, research datasets, and deal models need registration before circulation, which requires an ongoing feed from the asset lifecycle.
Enforcement scope must also follow the full AI workflow. Sensitive content can appear in a prompt, attached file, model response, retrieval step, memory, or downstream tool call. Browser sessions to personal accounts, desktop AI assistants running as native applications, and agents invoking tools over AI-native protocols each create paths where perimeter-only controls lack full interaction context. The program must cover those paths if its content signatures are to become enforceable protection.
Each interaction also needs an audit trail recording what matched, when, by whom, and through which channel. That evidence supports investigation and demonstrates that the control worked. Fingerprinting without auditability is not defensible in a legal or regulatory context. The Waymo vs. Uber settlement, worth hundreds of millions of dollars in equity, illustrates the stakes of being able to demonstrate what was taken and when.
Finally, candidate events need automatic investigation before they become human alerts. More fingerprint coverage should not automatically create more analyst work. Content identity, user role, behavioral timeline, and destination should arrive together so the analyst has the basic facts needed to assess risk. The practical standard is continuous recognition joined to continuous context. That is what turns fingerprinting from a record of protected content into an operational control for unlabeled IP.